What AZIMUTH is
AZIMUTH is a business intelligence platform that models the global orbital launch market. It is provider-agnostic by design: instead of tracking one company, it models the whole market, so that any launch vehicle can be set as the focus and benchmarked against the field. The same underlying model serves competitive benchmarking, program planning, and plain market research.
The guiding question is a stakeholder's. If you are evaluating a new heavy-lift vehicle, how does it actually stand against the rest of the market on cadence, reliability, reuse, and mass to orbit? That question is what every part of the model is built to answer.
The views
On top of the model, the app has five views:
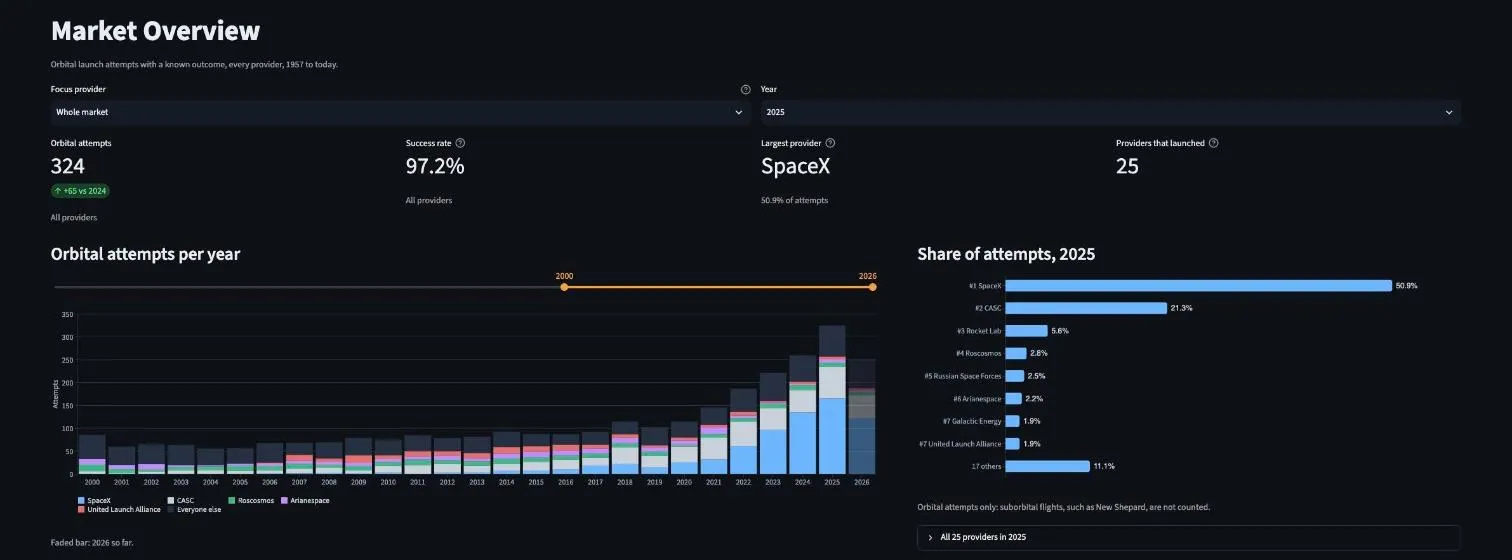
Market Overview
The current state of the launch market across providers, vehicles, and mission types.
The Maturation Race
How vehicles progress from first flight toward operational reliability, compared across programs.
Scenario Simulator
Adjust assumptions and watch a program's competitive position shift.
Vehicles
One page per rocket: its record, recent form against its lifetime, versions, and full launch history, with one click to simulate its future.
Ask AZIMUTH
Questions in plain language, in English or Spanish, answered from the same data as the rest of the app.
Where it stands
All eight phases, 0 to 7, are complete and the app is live. Here is what each phase delivered.
Lakehouse architecture
The platform will follow a medallion architecture on Databricks: raw launch data will land in bronze, get cleaned and conformed in silver, and be modeled into an analytics-ready star schema in gold with dbt, with data-quality tests guarding every layer boundary.
Since November 2026 the daily refresh runs the same dbt project on DuckDB inside GitHub Actions, because Databricks Free Edition stopped reliably starting compute for scheduled jobs. The layers, models and tests are unchanged, and the output was checked identical before the switch. The build log post Moving the daily refresh off Databricks explains why and how.
The data model
The gold layer is dimensionally modeled around a single fact table, fct_launches. The grain is one row per launch attempt, keyed on the launch UUID. Five conformed dimensions hang off it: date, provider, vehicle, orbit, and launch site. The mission attributes landed on the fact itself as degenerate attributes rather than a dimension of their own. Every question the platform answers (cadence per provider, reliability by vehicle, reuse rates over time, mass to orbit by destination) resolves to measures on that grain sliced by these dimensions.
Two relationships in the source are genuinely many-to-many, program and configuration families, so they are parked for a later version rather than forced into v1.
Timeline
Read the Launch Library 2 API closely, drafted the medallion schema, made the scope decisions in writing, and ran a first data-integrity check. Deliverable: a written scope document in the repo.
Pulled the full launch history from Launch Library 2: 76 pages, 7,598 records, throttled to the API's rate limit over roughly five hours. Built the loader to be resumable and idempotent, with a load audit table recording every run. Verified by running the same load twice: the second run inserted 0 rows and updated 0 rows.
Re-ran the Phase 0 data checks against all 7,598 launches, which overturned the orbital-scope rule and produced a curated, human-reviewed vehicle classification seed (485 configurations). Built the dbt staging model, six data-quality tests, and CI on GitHub Actions, green on the first real run.
Built the dimensional model: five dimensions (date, provider, vehicle, orbit, launch site) and the launch fact table, in a dedicated gold schema, under referential integrity tests, rebuilt by CI on every push. Providers enriched with country and sector, vehicles with disambiguated full names, and the orbit coverage gap made visible through an explicit "Not published" member.
Cadence, market share, and reliability by flight number, by configuration and by family. Every reliability figure carries a 95% Wilson interval, plus a Kaplan-Meier survival model validated against Python's lifelines and an era-matched benchmark per vehicle. CI now deploys to production schemas after all tests pass.
A daily scheduled refresh that loads only launches changed since the last run, then rebuilds, tests and deploys the models. Every run checks completeness against the source's own count and data freshness, and names any new vehicle that needs classifying.
Market Overview, The Maturation Race and the Scenario Simulator, plus a Methodology page, live on Streamlit. Neutral by default, with any provider selectable as the focus. The simulator is backtested against how real vehicles performed after five past dates.
Questions in plain language, answered from the same data as the app, with follow-up questions, a report button for wrong answers, and a 39-question test that runs after every deploy. The same phase added a page for every vehicle and shareable simulator scenarios.
Databricks Free Edition stopped starting compute for the scheduled refresh. The same dbt project now runs daily on DuckDB in GitHub Actions, with raw data kept as parquet in the repository. Output verified identical to Databricks before switching.